<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://theoteske.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://theoteske.github.io/" rel="alternate" type="text/html" /><updated>2026-08-23T14:35:36-05:00</updated><id>https://theoteske.github.io/feed.xml</id><title type="html">Theo Teske | Blog &amp;amp; Portfolio</title><subtitle>A technical blog and portfolio showcasing my computer science research at UMN, as well  as any projects I&apos;ve been working on and posts regarding algorithmic problem solving and machine learning.</subtitle><entry><title type="html">How Fine-Tuning Warps the Hidden Geometry of Transformers</title><link href="https://theoteske.github.io/blog/2026/08/fine-tuning-warps-geometry/" rel="alternate" type="text/html" title="How Fine-Tuning Warps the Hidden Geometry of Transformers" /><published>2026-08-23T00:00:00-05:00</published><updated>2026-08-23T00:00:00-05:00</updated><id>https://theoteske.github.io/blog/2026/08/fine-tuning-warps-geometry</id><content type="html" xml:base="https://theoteske.github.io/blog/2026/08/fine-tuning-warps-geometry/"><![CDATA[<p>A transformer is trained to predict tokens, but in the process it learns something richer than a next-token probability distribution. It learns a geometry over tokens and contexts. Hidden states become points in a high-dimensional space, encoding semantic, syntactic, and task-specific information as directions, distances, subspaces, and spectra.</p>

<p>This geometry matters because downstream behavior is often decided by simple operations on these representations, such as linear heads, cosine similarity, nearest-neighbor retrieval, or clustering. If the representation space collapses into a narrow cone, cosine similarity becomes less informative. If fine-tuning concentrates label information in a few principal directions, removing those directions can destroy performance. If LoRA introduces new singular directions, those directions can explain both adaptation and forgetting.</p>

<p>This post gives a compact geometric view of pre-training and fine-tuning, and briefly covers scalable validation.</p>

<p>To make the discussion concrete, I include a small case study comparing <code class="language-plaintext highlighter-rouge">distilbert-base-uncased</code> with <code class="language-plaintext highlighter-rouge">distilbert-base-uncased-finetuned-sst-2-english</code> on GLUE/SST-2. You can reproduce this experiment and generate the visualizations using the code in the accompanying <a href="https://github.com/theoteske/transformer-geometry-sst2">GitHub repository</a>.</p>

<h2 id="transformer-representations-have-geometry">Transformer representations have geometry</h2>

<p>Let $\mathcal V$ be a vocabulary and let $d$ be the hidden dimension. The input embedding matrix is</p>

\[E_{\mathrm{in}} \in \mathbb{R}^{|\mathcal V|\times d},\]

<p>so each token index is mapped to a vector in $\mathbb{R}^d$. For a sequence of length $T$, the hidden states at layer $\ell$ are</p>

\[H^{(\ell)} \in \mathbb{R}^{T\times d}.\]

<p>A self-attention head computes</p>

\[\operatorname{Attention}(Q,K,V_{\mathrm{val}}) = \operatorname{softmax}\left(\frac{QK^\top}{\sqrt{d_k}}\right)V_{\mathrm{val}},\]

<p>where $Q$, $K$, and $V_{\mathrm{val}}$ are query, key, and value projections of the current hidden states.</p>

<p>The model also has an output unembedding or language-model head</p>

\[U \in \mathbb{R}^{|\mathcal V|\times d},\]

<p>whose rows act as token classifiers. Given a hidden state $h$, the logit for token $v$ is typically</p>

\[z_v(h)=u_v^\top h+b_v.\]

<p>Some architectures tie $U$ and $E_{\mathrm{in}}$; others keep them separate.</p>

<p>There are two related geometries worth separating:</p>

<ol>
  <li><strong>Activation geometry</strong>, which is the point cloud formed by hidden states $h_i$ across tokens, positions, layers, and contexts.</li>
  <li><strong>Weight geometry</strong>, or the geometry of learned matrices such as $E_{\mathrm{in}}$, $U$, attention projections, MLP weights, and low-rank adaptation matrices.</li>
</ol>

<p>Fine-tuning changes both. Full fine-tuning moves all weights, while PEFT methods such as LoRA move only a small number of parameters, making the resulting geometric deformation easier to inspect.</p>

<h2 id="isotropy-and-anisotropy">Isotropy and anisotropy</h2>

<p>A basic geometric question is whether a representation uses its dimensions evenly.</p>

<p>Given centered hidden states $X\in\mathbb{R}^{N\times d}$, with rows</p>

\[x_i=h_i-\bar h,\]

<p>the empirical covariance is</p>

\[\widehat{\Sigma} = \frac{1}{N-1}X^\top X.\]

<p>The representation is approximately <strong>isotropic</strong> when</p>

\[\widehat{\Sigma}\approx \sigma^2 I,\]

<p>meaning variance is spread roughly evenly across directions. Equivalently, no small set of principal components dominates the representation.</p>

<p>If $\lambda_1,\ldots,\lambda_d$ are the covariance eigenvalues, a useful summary statistic is the participation-ratio effective rank</p>

\[r_{\mathrm{eff}} = \frac{\left(\sum_i \lambda_i\right)^2}{\sum_i \lambda_i^2}.\]

<p>This quantity is scale-invariant. It equals $d$ when all eigenvalues are equal and approaches $1$ when one direction carries almost all variance.</p>

<p>Transformer representations are often <strong>anisotropic</strong>, meaning that hidden states can share a large common component, occupy a narrow cone, or have a covariance spectrum dominated by a few directions. These are related but not identical phenomena. A large mean vector affects raw cosine similarity; a concentrated covariance spectrum affects effective rank and explained variance. A representation can look good under one diagnostic and degenerate under another.</p>

<p>This phenomenon of anisotropy in transformer representations is referred to as <strong>representation degeneration</strong> and has been observed in contextual word representations and language generation models<sup><a href="#ref5">[5]</a>, <a href="#ref6">[6]</a>, <a href="#ref7">[7]</a></sup>. Similar effects have also been reported outside natural language text, including in protein language models, suggesting that anisotropy is a broader interaction among architecture, data distribution, objective, normalization, and optimization<sup><a href="#ref8">[8]</a></sup>.</p>

<p>A common symptom is high average cosine similarity between unrelated hidden states. If</p>

\[h_i = m+\varepsilon_i\]

<p>and the common component $m$ is large relative to the variation $\varepsilon_i$, then many pairwise cosines become artificially high. This makes angular distance less useful for semantic discrimination.</p>

<p>However, it’s important to note that low average cosine is not evidence of isotropy. A simple counterexample makes this clear. Suppose</p>

\[h_i = y_i v, \qquad y_i\in\{-1,+1\},\]

<p>with roughly balanced signs. The covariance is rank one, so the representation is maximally anisotropic in the sense that all variation lies along the single direction $v$, and $r_{\mathrm{eff}}=1$. But the average pairwise cosine is close to zero, because pairs with the same sign contribute $+1$, pairs with opposite signs contribute $-1$, and the two effects mostly cancel. If the signs are exactly balanced, the average over distinct pairs is $-1/(N-1)$, essentially zero for large $N$.</p>

<h2 id="why-anisotropy-can-arise">Why anisotropy can arise</h2>

<p>One mechanism comes directly from the softmax objective.</p>

<p>For an autoregressive language model,</p>

\[p_\theta(v\mid c) = \frac{\exp(u_v^\top h_c+b_v)}{\sum_{w\in\mathcal V}\exp(u_w^\top h_c+b_w)},\]

<p>where $h_c$ is the hidden state for context $c$. For a single training example with target token $y$, the cross-entropy gradient with respect to output vector $u_v$ is</p>

\[\nabla_{u_v}\bigl[-\log p_\theta(y\mid c)\bigr] = \left(p_\theta(v\mid c)-\mathbf 1\{v=y\}\right)h_c.\]

<p>For a rare token $v$, most contexts are negative examples, in which $v\neq y$. Gradient descent therefore repeatedly updates $u_v$ in directions that reduce its logit on the bulk of hidden states.</p>

<p>Gao et al. describe a related degeneration mechanism<sup><a href="#ref7">[7]</a></sup>. Suppose that there exists a direction $a$ such that</p>

\[h_c^\top a &lt; 0\]

<p>for all relevant hidden states $h_c$. Then moving a rare token’s output embedding in the $a$ direction lowers that token’s logit across those contexts. A separating-hyperplane argument can supply such a direction when the origin lies outside the convex hull of the hidden-state cloud.</p>

<p>This helps explain why rare-token output embeddings can acquire common directions under softmax training. If input embeddings and output unembeddings are tied, this output-side pressure can also leak into the input embedding geometry.</p>

<p>This is not the only source of anisotropy, but it is an important example showing that degeneration can be a natural byproduct of the optimization process rather than a mere numerical accident.</p>

<h2 id="fine-tuning-reorganizes-geometry">Fine-tuning reorganizes geometry</h2>

<p>Fine-tuning should not be understood as simply repairing pre-training anisotropy. It often reorganizes the representation space around the downstream objective.</p>

<p>In full fine-tuning, the model is initialized from pre-trained weights $\theta_{\mathrm{pre}}$, and all parameters are updated on a downstream dataset $\mathcal D_{\mathrm{FT}}$ by the rule</p>

\[\theta_{t+1} = \theta_t - \eta \nabla_\theta \mathcal L_{\mathrm{FT}}(\theta_t;\mathcal D_{\mathrm{FT}}).\]

<p>At the activation level, fine-tuning changes the covariance of hidden states. For centered samples from layer $\ell$,</p>

\[X^{(\ell)}\in\mathbb{R}^{N\times d},\]

<p>define</p>

\[C^{(\ell)} = \frac{1}{N-1}(X^{(\ell)})^\top X^{(\ell)}.\]

<p>The eigenvalues of $C^{(\ell)}$ describe how concentrated the representation is. The eigenvectors describe where that variance lies.</p>

<p>Before fine-tuning, leading principal components may encode broad or nuisance statistics such as token frequency, punctuation, sentence length, and so on. This helps explain why post-processing methods such as <strong>All-but-the-Top</strong>, which center embeddings and remove leading principal components, can improve some static embedding and similarity benchmarks<sup><a href="#ref9">[9]</a></sup>.</p>

<p>After fine-tuning, however, dominant directions can become task-relevant. In BERT-like models, fine-tuning may concentrate information useful for natural language inference, semantic textual similarity, or classification into high-variance directions<sup><a href="#ref3">[3]</a></sup>. The representation may become less isotropic while becoming better for the task.</p>

<p>This provides evidence that removing top principal components is not automatically a cleanup step. If the top components encode nuisance structure, removing them can help, but if they encode label-relevant information, removing them can destroy performance.</p>

<p>A task-aware ablation is better. If $V_k=[v_1,\ldots,v_k]$ contains the top $k$ principal directions of the centered representation, test the intervention</p>

\[h \mapsto \bar h + (I - V_kV_k^\top)(h-\bar h)\]

<p>on the downstream metric, and also test removing low-variance directions. Then, report geometry and task performance together. Isotropy alone is not the objective.</p>

<h2 id="case-study-of-fine-tuning-on-distilberts-geometry">Case study of fine-tuning on DistilBERT’s geometry</h2>

<p>The claim above is easy to state but easy to misuse. So let us look at a small diagnostic experiment.</p>

<h3 id="experimental-setup">Experimental setup</h3>

<p>I compared two public checkpoints:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">distilbert-base-uncased</code>, the pre-trained DistilBERT backbone<sup><a href="#ref15">[15]</a></sup>;</li>
  <li><code class="language-plaintext highlighter-rouge">distilbert-base-uncased-finetuned-sst-2-english</code>, the same architecture fine-tuned for SST-2 sentiment classification.</li>
</ul>

<p>The evaluation set was the full GLUE/SST-2 validation split, $N=872$ examples<sup><a href="#ref16">[16]</a>, <a href="#ref17">[17]</a></sup>. The script did not train either model; rather, it extracted the $[\mathrm{CLS}]$ hidden state at every hidden-state index, which is the embedding output plus the six DistilBERT transformer layers.</p>

<p>For each layer, it computed:</p>

<ul>
  <li>mean norm $|\bar h|_2$;</li>
  <li>average raw pairwise cosine;</li>
  <li>average centered pairwise cosine;</li>
  <li>covariance eigenvalue spectrum;</li>
  <li>participation-ratio effective rank;</li>
  <li>top-$k$ explained variance;</li>
  <li>pre-trained/fine-tuned PCA subspace overlap;</li>
  <li>task accuracy after ablating principal components from the fine-tuned final-layer $[\mathrm{CLS}]$ states.</li>
</ul>

<p>The embedding-layer $[\mathrm{CLS}]$ vector is constant across examples in this architecture, so its covariance is zero.</p>

<h3 id="summary-metrics">Summary metrics</h3>

<p>The final-layer $[\mathrm{CLS}]$ geometry changed sharply after fine-tuning.</p>

<table>
  <thead>
    <tr>
      <th>Final-layer state</th>
      <th>SST-2 accuracy</th>
      <th>$|\bar h|_2$</th>
      <th>$\operatorname{tr}(\widehat\Sigma)$</th>
      <th>Effective rank</th>
      <th>Top-1 variance</th>
      <th>Top-10 variance</th>
      <th>Raw avg. cosine</th>
      <th>Centered avg. cosine</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Pre-trained backbone</td>
      <td>—</td>
      <td>11.77</td>
      <td>12.58</td>
      <td>25.82</td>
      <td>13.8%</td>
      <td>48.4%</td>
      <td>0.917</td>
      <td>0.0002</td>
    </tr>
    <tr>
      <td>Fine-tuned classifier</td>
      <td>0.911</td>
      <td>7.59</td>
      <td>196.24</td>
      <td>1.62</td>
      <td>78.3%</td>
      <td>90.3%</td>
      <td>0.230</td>
      <td>0.0016</td>
    </tr>
  </tbody>
</table>

<p>The pre-trained backbone has no SST-2 classification head, so I do not report a task accuracy for it. The fine-tuned checkpoint reaches $91.1\%$ accuracy on these 872 validation examples.</p>

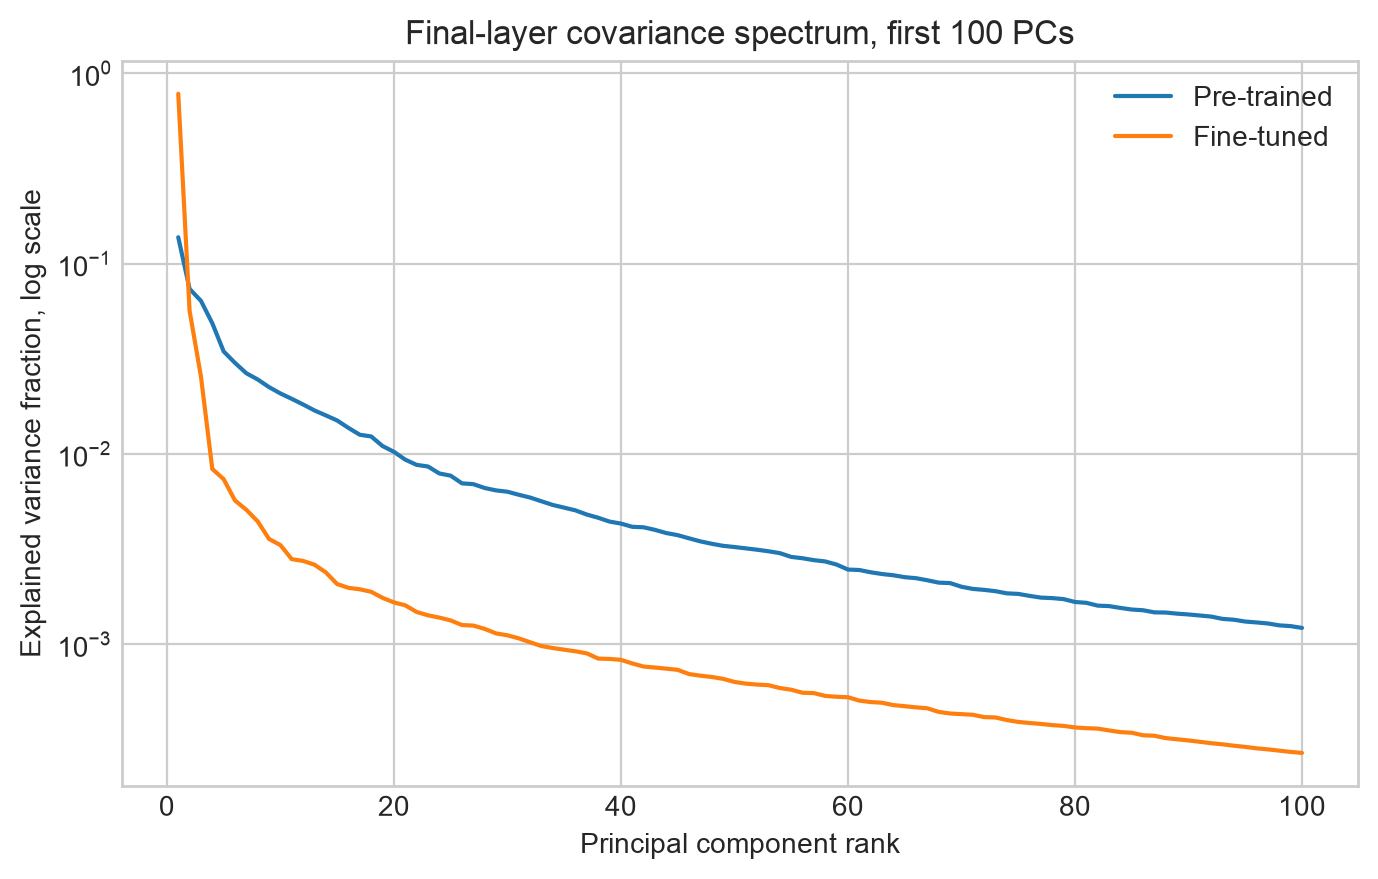
<p>Raw average cosine drops from $0.917$ to $0.230$, which by itself might suggest that the fine-tuned representation is less anisotropic. But the covariance spectrum says the opposite, as the final fine-tuned $[\mathrm{CLS}]$ states are much more spectrally concentrated. The top principal component alone explains $78.3\%$ of the variance, and the top ten explain $90.3\%$. The effective rank falls from $25.82$ to $1.62$ out of $768$ dimensions.</p>

<p>This is not surprising. A representation can have near-zero average centered cosine while being almost one-dimensional, as long as examples are distributed on both sides of the dominant axis. For a sentiment classifier, that is a plausible geometry, as positive and negative examples may separate along a high-variance direction, causing pairwise cosine contributions to cancel in the average. This demonstrates concretely why relying solely on average cosine to measure anisotropy can be misleading.</p>

<p><img src="/assets/images/last_layer_spectrum.png" alt="Final-layer covariance spectrum before and after fine-tuning." /></p>

<p><strong>Figure 1. Covariance spectra before and after fine-tuning.</strong> Eigenvalues are normalized by total variance. A steeper curve means variance is more concentrated in a small number of directions.</p>

<p>The subspace-overlap diagnostic reinforces this finding. For top-$k$ PCA bases $A$ and $B$, I measured</p>

\[\frac{\|A^\top B\|_F^2}{k}.\]

<p>This equals $1$ for identical $k$-dimensional subspaces and decreases as the subspaces diverge. Ignoring the degenerate embedding layer, the top-10 pre-trained/fine-tuned overlap was about $0.69$ after the first transformer layer, $0.49$ after the fourth, and $0.20$ in the final layer. The top-50 overlap in the final layer was $0.35$. Fine-tuning therefore did not merely rescale the old leading directions; in fact, it substantially reorganized the principal subspaces in later layers.</p>

<h3 id="principal-component-ablation">Principal-component ablation</h3>

<p>The decisive question is whether the new dominant directions are useful or harmful.</p>

<p>To test this, I modified the fine-tuned final-layer $[\mathrm{CLS}]$ states by removing principal components and then passed the modified states through the frozen DistilBERT classification head via the intervention</p>

\[h \mapsto \bar h + (I - V_kV_k^\top)(h-\bar h).\]

<p>This intervention was applied only at the final representation, without rerunning the transformer. It tests how much the trained classifier depends on particular representation directions.</p>

<table>
  <thead>
    <tr>
      <th>Intervention on fine-tuned final $[\mathrm{CLS}]$</th>
      <th>SST-2 accuracy</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>No ablation</td>
      <td>0.911</td>
    </tr>
    <tr>
      <td>Remove top 1 PC</td>
      <td>0.513</td>
    </tr>
    <tr>
      <td>Remove top 10 PCs</td>
      <td>0.509</td>
    </tr>
    <tr>
      <td>Remove top 100 PCs</td>
      <td>0.509</td>
    </tr>
    <tr>
      <td>Remove bottom 1 PC</td>
      <td>0.911</td>
    </tr>
    <tr>
      <td>Remove bottom 100 PCs</td>
      <td>0.911</td>
    </tr>
  </tbody>
</table>

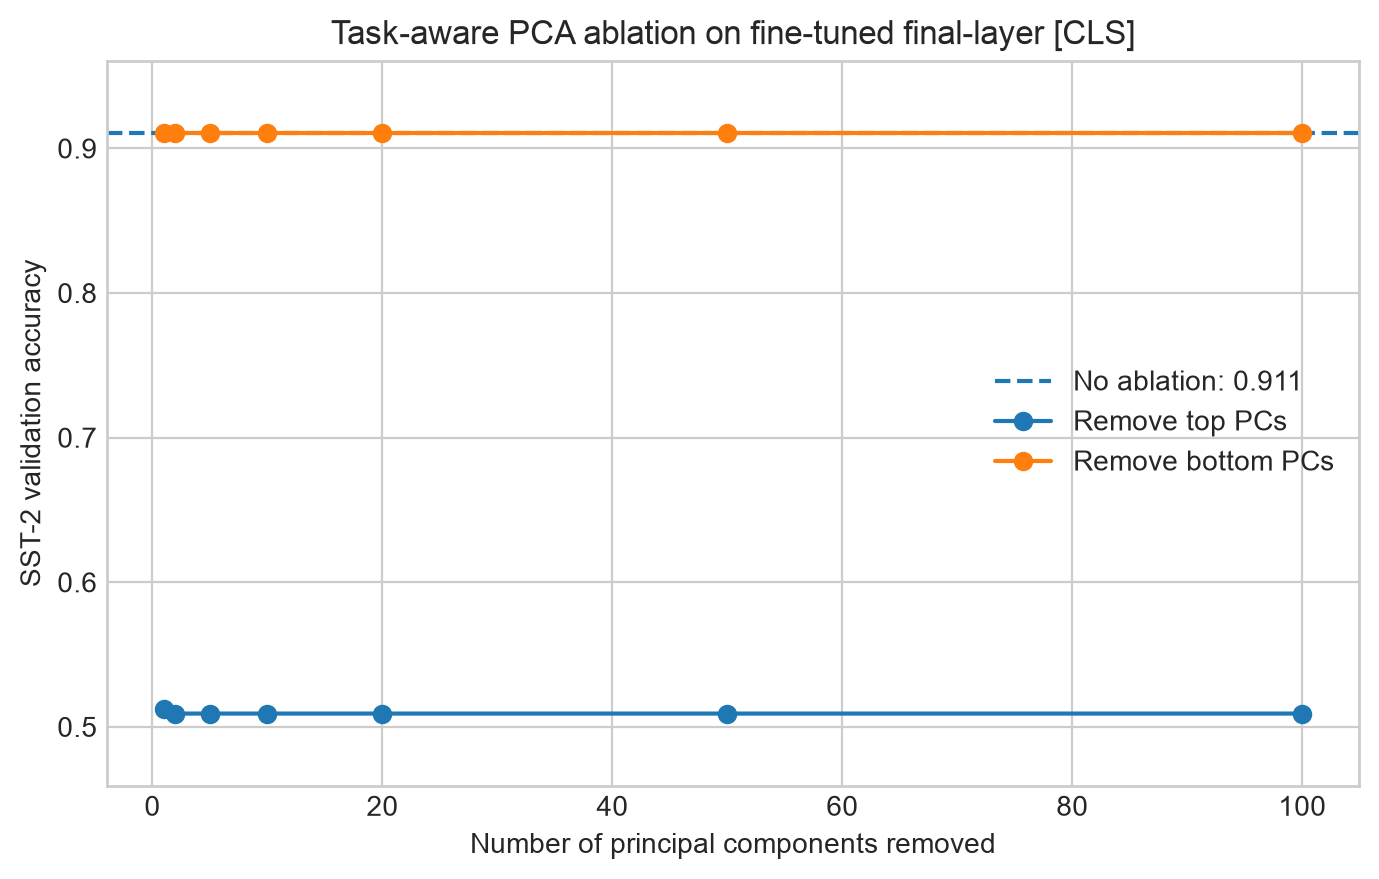
<p>Removing the top principal component alone drops accuracy from $91.1\%$ to roughly chance. Removing additional top components does not substantially worsen it, because the main decision-relevant direction has already been removed. By contrast, removing as many as 100 bottom principal components leaves accuracy unchanged.</p>

<p><img src="/assets/images/pc_ablation_accuracy.png" alt="Task performance after principal-component ablation." /></p>

<p><strong>Figure 2. Task performance after principal-component ablation.</strong> Removing the top principal components tests whether high-variance directions encode nuisance structure or task-relevant information. Removing bottom components serves as a control.</p>

<p>This is the main lesson of the case study. The final fine-tuned representation is highly anisotropic in the centered covariance sense, but that anisotropy is not merely collapse. At least for the SST-2 classifier, the dominant direction is task-critical.</p>

<p>There is one methodological caveat. In this small blog experiment, PCA directions were estimated on the same validation activations that were later ablated. The labels were not used to fit the PCs, but a stricter benchmarking evaluation should fit PCA directions on a separate calibration split and evaluate ablations on held-out examples. The result should therefore be read as an illustrative diagnostic, not as a universal claim about DistilBERT or SST-2.</p>

<h3 id="takeaways-from-the-case-study">Takeaways from the case study</h3>

<p>The experiment illustrates three main points.</p>

<ol>
  <li>Fine-tuning changed geometry measurably. Effective rank, covariance spectra, cosine statistics, and PCA subspaces all shifted, especially in later layers.</li>
  <li>Raw cosine alone was misleading. The fine-tuned representation had much lower raw average cosine but a far more concentrated centered covariance spectrum.</li>
  <li>Task-aware ablation was essential. The top principal direction looked like a collapse under an isotropy metric, but removing it destroyed task performance. In this run, the dominant direction was not disposable nuisance variation; it was central to the classifier.</li>
</ol>

<h2 id="lora-as-an-inspectable-low-rank-weight-change">LoRA as an inspectable low-rank weight change</h2>

<p>The case study above looked at activation geometry under a fully fine-tuned checkpoint. LoRA gives an especially clean way to study geometry on the weight side.</p>

<p>Parameter-efficient fine-tuning methods reduce adaptation cost by training only a small number of parameters. The most common example is <strong>LoRA</strong><sup><a href="#ref1">[1]</a></sup>.</p>

<p>For a frozen weight matrix</p>

\[W_0\in\mathbb{R}^{d_{\mathrm{out}}\times d_{\mathrm{in}}},\]

<p>LoRA learns</p>

\[W = W_0+\Delta W,\]

<p>where</p>

\[\Delta W = \frac{\alpha}{r}BA,\]

<p>with</p>

\[B\in\mathbb{R}^{d_{\mathrm{out}}\times r}, \qquad A\in\mathbb{R}^{r\times d_{\mathrm{in}}}, \qquad r\ll \min(d_{\mathrm{out}},d_{\mathrm{in}}).\]

<p>Thus</p>

\[\operatorname{rank}(\Delta W)\le r.\]

<p>Geometrically,</p>

\[\Delta W x = \frac{\alpha}{r}B(Ax).\]

<p>The update first reads an $r$-dimensional sketch $Ax$ of the input, then writes back through the column space of $B$. This makes LoRA easier to inspect because the learned change is concentrated in a small number of input and output directions.</p>

<p>Using the singular value decomposition,</p>

\[\Delta W = \sum_{i=1}^r s_i p_i q_i^\top,\]

<p>one can ask:</p>

<ul>
  <li>Which input directions $q_i$ does the adaptation read?</li>
  <li>Which output directions $p_i$ does it write to?</li>
  <li>Are these directions aligned with the pre-trained matrix $W_0$?</li>
  <li>Do they correspond to task improvement, forgetting, or both?</li>
</ul>

<p>Recent work comparing LoRA and full fine-tuning identifies <strong>intruder dimensions</strong> in some adapted matrices<sup><a href="#ref11">[11]</a></sup>. These are high-ranking singular directions of the adapted matrix $W_0+\Delta W$ that have large singular values but weak alignment with the corresponding singular subspaces of $W_0$.</p>

<p>Mathematically, if $\hat u_i,\hat v_i$ are singular vectors of the adapted matrix, one can measure their alignment with pre-trained left and right singular subspaces using projection norms such as</p>

\[\|P_{\mathrm{pre}}\hat u_i\|_2^2 \qquad\text{and}\qquad \|Q_{\mathrm{pre}}\hat v_i\|_2^2.\]

<p>Large singular value combined with weak pre-trained alignment is a warning sign. In reported interventions, damping singular values associated with intruder directions partially restored pre-training behavior while preserving much of the downstream gain<sup><a href="#ref11">[11]</a></sup>.</p>

<p>A related issue appears in multimodal fine-tuning. Vision and text encoders can occupy separated regions of a shared latent space, a phenomenon known as a <strong>modality gap</strong><sup><a href="#ref12">[12]</a></sup>. Under extreme low-rank constraints, such as rank-1 LoRA, a random direction is unlikely to align with a fixed high-dimensional gap direction. If $a$ is a random unit vector in $d$ dimensions and $g$ is a fixed unit direction, then</p>

\[\mathbb E[(a^\top g)^2]=\frac1d,\]

<p>so the useful projection is typically very small.</p>

<p>This matters because standard LoRA often initializes one factor to zero. For example, if $B=0$ and $A$ is random, then $\Delta W=0$ initially. If $G=\nabla_W\mathcal L$, then at initialization</p>

\[\nabla_B\mathcal L = \frac{\alpha}{r}GA^\top, \qquad \nabla_A\mathcal L = \frac{\alpha}{r}B^\top G = 0.\]

<p>Thus, early gradient flow is shaped by the random row space of $A$. In rank-1 settings, poor alignment can slow or stall adaptation. Geometry-guided methods such as <strong>Gap-Init</strong> estimate the modality-gap direction and initialize the LoRA direction accordingly<sup><a href="#ref2">[2]</a></sup>.</p>

<h2 id="architecture-and-regularization">Architecture and regularization</h2>

<p>Anisotropy is common, but it is not inevitable. It depends on architecture, objective, normalization, data, and optimization. Recent analyses using model suites such as Pythia are useful because they allow comparisons across model scale and training checkpoints<sup><a href="#ref13">[13]</a>, <a href="#ref14">[14]</a></sup>.</p>

<h3 id="untied-embeddings-and-unembeddings">Untied embeddings and unembeddings</h3>

<p>Weight tying makes the same token vectors serve two roles:</p>

<ol>
  <li>input embeddings for computation;</li>
  <li>output classifiers for the softmax objective.</li>
</ol>

<p>This is parameter-efficient, but it couples input geometry directly to output-classification pressure. Rare-token and softmax effects on $U$ can affect $E_{\mathrm{in}}$ when the matrices are tied, as covered in the Gao et al. discussion.</p>

<p>Untying $E_{\mathrm{in}}$ and $U$ gives the model separate degrees of freedom for input representation and output classification. In the cited Pythia-related analysis, untied embeddings correlate with improved global isotropy in larger models, at the cost of additional parameters<sup><a href="#ref13">[13]</a>, <a href="#ref14">[14]</a></sup>.</p>

<h3 id="final-layernorm-geometry">Final LayerNorm geometry</h3>

<p>Layer normalization also has a clean geometric interpretation. For a hidden state $h\in\mathbb{R}^d$, ignoring the usual numerical $\epsilon$, LayerNorm computes</p>

\[\operatorname{LayerNorm}(h) = g\odot \frac{h-\mu\mathbf 1}{\sigma} + b,\]

<p>where</p>

\[\mu=\frac1d\mathbf 1^\top h, \qquad \sigma^2=\frac1d\|h-\mu\mathbf 1\|_2^2,\]

<p>and $g,b\in\mathbb{R}^d$ are learned gain and bias parameters.</p>

<p>Before gain and bias, the normalized vector</p>

\[x=\frac{h-\mu\mathbf 1}{\sigma}\]

<p>satisfies</p>

\[\mathbf 1^\top x=0, \qquad \|x\|_2^2=d.\]

<p>So LayerNorm first maps each vector to a fixed-radius sphere inside the hyperplane orthogonal to $\mathbf 1$. The learned gain and bias then stretch and translate this set.</p>

<p>If</p>

\[y=g\odot x+b\]

<p>and all $g_i\neq 0$, then</p>

\[\sum_{i=1}^d \frac{y_i-b_i}{g_i}=0,\]

<p>or equivalently,</p>

\[\sum_{i=1}^d \frac{y_i}{g_i} = \sum_{i=1}^d \frac{b_i}{g_i}.\]

<p>Thus post-LayerNorm states lie in an affine hyperplane. A large shared offset from the bias term can increase raw cosine similarity by adding a common component. Conversely, a final LayerNorm that avoids a large shared offset can improve apparent isotropy relative to preceding layers<sup><a href="#ref13">[13]</a></sup>.</p>

<p>Strictly, because the post-LayerNorm states lie in an affine hyperplane, their centered covariance is singular in the normal direction</p>

\[n=\left(\frac1{g_1},\ldots,\frac1{g_d}\right).\]

<p>So isotropy here should be interpreted relative to the allowed $(d-1)$-dimensional subspace.</p>

<h3 id="geometry-aware-regularization">Geometry-aware regularization</h3>

<p>When architecture cannot be changed, one can regularize geometry during training or fine-tuning.</p>

<p>A covariance-based approach adds an isotropy-related penalty to the task loss. For example, <strong>I-STAR</strong> uses shrinkage covariance estimates to define a stable differentiable isotropy score<sup><a href="#ref4">[4]</a></sup>. A typical objective has the form</p>

\[\mathcal L = \mathcal L_{\mathrm{task}} + \lambda\bigl(1-S_{\mathrm{iso}}(H)\bigr).\]

<p>Contrastive learning and related regularizers can also spread representations more uniformly in some settings<sup><a href="#ref10">[10]</a></sup>.</p>

<p>The important caveat is that maximal isotropy is not always best. As established before, fine-tuned models may intentionally concentrate useful task information in high-variance directions. In these cases, controlled anisotropy can be a feature, not a flaw.</p>

<h2 id="scalable-geometric-validation">Scalable geometric validation</h2>

<p>If representation geometry matters, it should be monitored during training and fine-tuning. The challenge is scale.</p>

<p>A full pairwise distance or cosine matrix costs $O(N^2)$ memory and $O(N^2d)$ time for $N$ vectors in $d$ dimensions. This becomes infeasible quickly.</p>

<p>Fortunately, many useful diagnostics do not require all pairwise distances.</p>

<h3 id="streaming-covariance">Streaming covariance</h3>

<p>Mean and covariance can be estimated in a streaming or batched way. If a batch summary contains count $n$, mean $\mu$, and scatter matrix</p>

\[S=\sum_i (x_i-\mu)(x_i-\mu)^\top,\]

<p>then two summaries $(n_a,\mu_a,S_a)$ and $(n_b,\mu_b,S_b)$ can be merged by setting</p>

\[n=n_a+n_b,\]

\[\mu=\frac{n_a\mu_a+n_b\mu_b}{n},\]

<p>and</p>

\[S = S_a+S_b + \frac{n_an_b}{n} (\mu_b-\mu_a)(\mu_b-\mu_a)^\top.\]

<p>Then</p>

\[\widehat{\Sigma}=\frac{S}{n-1}.\]

<p>Forming the full covariance costs $O(Nd^2)$ time and $O(d^2)$ memory. If only the top $k$ directions are needed, randomized PCA or streaming sketching can often reduce the cost to roughly $O(Ndk)$.</p>

<h3 id="average-cosine-without-all-pairs">Average cosine without all pairs</h3>

<p>Even average pairwise cosine similarity can be computed without enumerating all pairs. If $u_i$ are normalized vectors, then</p>

\[\frac{1}{N(N-1)} \sum_{i\ne j}u_i^\top u_j = \frac{\left\|\sum_i u_i\right\|^2-N}{N(N-1)}.\]

<p>This provides an $O(Nd)$ diagnostic for one common symptom of anisotropy. However, this statistic is weak as a general anisotropy measure. As discussed previously, and as evidenced by the DistilBERT case study, a low average pairwise cosine similarity can occur simultaneously with highly concentrated covariance. This suggests the need for other methods of sublinear geometric validation, but covering these is beyond the scope of this post.</p>

<h3 id="a-practical-checklist">A practical checklist</h3>

<p>A useful validation pipeline should track geometry and task performance together. Some useful metrics to cover include:</p>

<ol>
  <li>Mean shift: $|\bar h|_2$ by layer and checkpoint.</li>
  <li>Cosine symptoms: average raw cosine and centered cosine.</li>
  <li>Spectral concentration: top eigenvalue mass, effective rank, and explained variance curves.</li>
  <li>Subspace drift: overlap between pre-trained and fine-tuned principal subspaces.</li>
  <li>Task-aware ablations: remove top PCs, remove bottom PCs, and evaluate the downstream metric.</li>
  <li>LoRA diagnostics: inspect singular values of $\Delta W$ and $W_0+\Delta W$ and measure alignment with pre-trained singular subspaces.</li>
  <li>Multimodal alignment: in vision-language settings, measure whether low-rank updates align with modality-gap directions.</li>
</ol>

<p>The DistilBERT case study used all but the LoRA diagnostics and multimodal alignment from the above checklist. For LoRA fine-tuning, the same activation diagnostics can be combined with singular-direction diagnostics on the learned weight updates.</p>

<p>The goal of geometric monitoring of fine-tuning is not to maximize isotropy blindly. The goal is to distinguish harmful degeneration from meaningful task-specific geometry. A good fine-tuned model may be anisotropic because it has organized the representation space around the task, while a bad one may be anisotropic because it has collapsed. Geometry is how we tell the difference.</p>

<hr />

<h2 id="references">References</h2>

<ol>
  <li><a id="ref1"></a>Hu, E. J., Shen, Y., Wallis, P., Allen-Zhu, Z., Li, Y., Wang, S., Wang, L., &amp; Chen, W. (2022). <em>LoRA: Low-Rank Adaptation of Large Language Models</em>. ICLR 2022.</li>
  <li><a id="ref2"></a>Zhao, H., Han, C., &amp; Hovy, E. (2026). <em>When Is Rank-1 Enough? Geometry-Guided Initialization for Parameter-Efficient Fine-Tuning</em>. ICML 2026.</li>
  <li><a id="ref3"></a>Rajaee, S., &amp; Pilehvar, M. T. (2021). <em>How Does Fine-tuning Affect the Geometry of Embedding Space: A Case Study on Isotropy</em>. Findings of ACL: EMNLP 2021.</li>
  <li><a id="ref4"></a>Rudman, W., &amp; Eickhoff, C. (2024). <em>Stable Anisotropic Regularization</em>. ICLR 2024.</li>
  <li><a id="ref5"></a>Godey, N., Villemonte de la Clergerie, E., &amp; Sagot, B. (2023). <em>Is Anisotropy Inherent to Transformers?</em> arXiv:2306.07656.</li>
  <li><a id="ref6"></a>Ethayarajh, K. (2019). <em>How Contextual are Contextualized Word Representations?</em> EMNLP-IJCNLP 2019.</li>
  <li><a id="ref7"></a>Gao, J., He, D., Tan, X., Qin, T., Wang, L., &amp; Liu, T.-Y. (2019). <em>Representation Degeneration Problem in Training Natural Language Generation Models</em>. ICLR 2019.</li>
  <li><a id="ref8"></a>Hakim, S. A., Roy, K., &amp; Rahman, M. S. (2025). <em>A Look at the Isotropy of Pretrained Protein Language Models</em>. OpenReview preprint.</li>
  <li><a id="ref9"></a>Mu, J., &amp; Viswanath, P. (2018). <em>All-but-the-Top: Simple and Effective Postprocessing for Word Representations</em>. ICLR 2018.</li>
  <li><a id="ref10"></a>Qiu, R., Huang, Z., Yin, H., &amp; Wang, Z. (2022). <em>Contrastive Learning for Representation Degeneration Problem in Sequential Recommendation</em>. WSDM 2022.</li>
  <li><a id="ref11"></a>Shuttleworth, R., Andreas, J., Torralba, A., &amp; Sharma, P. (2024). <em>LoRA vs Full Fine-tuning: An Illusion of Equivalence</em>. arXiv:2410.21228.</li>
  <li><a id="ref12"></a>Liang, W., Zhang, Y., Kwon, Y., Yeung, S., &amp; Zou, J. (2022). <em>Mind the Gap: Understanding the Modality Gap in Multi-modal Contrastive Representation Learning</em>. NeurIPS 2022.</li>
  <li><a id="ref13"></a>Machina, A., &amp; Mercer, R. E. (2024). <em>Anisotropy is Not Inherent to Transformers</em>. Preprint manuscript.</li>
  <li><a id="ref14"></a>Biderman, S., Schoelkopf, H., Anthony, Q. G., Bradley, H., O’Brien, K., Hallahan, E., Khan, M. A., Purohit, S., Prashanth, U. S., Raff, E., Skowron, A., Sutawika, L., &amp; Van Der Wal, O. (2023). <em>Pythia: A Suite for Analyzing Large Language Models Across Training and Scaling</em>. ICML 2023.</li>
  <li><a id="ref15"></a>Sanh, V., Debut, L., Chaumond, J., &amp; Wolf, T. (2019). <em>DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter</em>. NeurIPS EMC$^2$ Workshop.</li>
  <li><a id="ref16"></a>Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., &amp; Bowman, S. R. (2019). <em>GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding</em>. ICLR 2019.</li>
  <li><a id="ref17"></a>Socher, R., Perelygin, A., Wu, J., Chuang, J., Manning, C. D., Ng, A. Y., &amp; Potts, C. (2013). <em>Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank</em>. EMNLP 2013.</li>
</ol>]]></content><author><name>Theo Teske</name></author><category term="Machine Learning" /><category term="NLP" /><category term="Transformers" /><category term="Fine-Tuning" /><category term="Model Interpretability" /><category term="Embeddings" /><category term="Representation Learning" /><summary type="html"><![CDATA[A transformer is trained to predict tokens, but in the process it learns something richer than a next-token probability distribution. It learns a geometry over tokens and contexts. Hidden states become points in a high-dimensional space, encoding semantic, syntactic, and task-specific information as directions, distances, subspaces, and spectra.]]></summary></entry><entry><title type="html">Fast Exponentiation and Modular Exponentiation</title><link href="https://theoteske.github.io/blog/2025/08/fast-exponentiation-and-modular-exponentiation/" rel="alternate" type="text/html" title="Fast Exponentiation and Modular Exponentiation" /><published>2025-08-28T00:00:00-05:00</published><updated>2025-08-28T00:00:00-05:00</updated><id>https://theoteske.github.io/blog/2025/08/fast-exponentiation-and-modular-exponentiation</id><content type="html" xml:base="https://theoteske.github.io/blog/2025/08/fast-exponentiation-and-modular-exponentiation/"><![CDATA[<p>I give an exposition of both the fast exponentiation and modular exponentiation algorithms, then we apply the latter to the LeetCode problem <a href="https://leetcode.com/problems/range-product-queries-of-powers/description/">2438. Range Product Queries of Powers</a>. The solution to this problem presented here differs substantially from the solution provided in the LeetCode editorial while still achieving optimal runtime and memory efficiency.</p>

<h2 id="fast-exponentiation">Fast Exponentiation</h2>

<p>Consider the following problem: given some integer base $x$ and some non-negative integer exponent $n$, efficiently compute the value of $x^n$, or $x$ raised to the power of $n$. Of course, the brute force solution involves $n$ multiplications by $x$, which will have $O(n)$ runtime efficiency. However, we can do better.</p>

<p>The core insight is that we can repeatedly halve the exponent rather than multiplying the base $n$ times, leading to logarithmic time complexity. We can summarize the <strong>fast exponentiation</strong> algorithm, also known as the method of <strong>repeated squaring</strong>, with the following recursion<sup><a href="#ref1">[1]</a></sup>:</p>

\[x^n = 
\begin{cases}
1 &amp; \text{if } n = 0 \\
x^{n/2} \cdot x^{n/2} &amp; \text{if } n \text{ is even} \\
x \cdot x^{(n-1)/2} \cdot x^{(n-1)/2} &amp; \text{if } n \text{ is odd}
\end{cases}\]

<p>In each recursive call, we solve the subproblem with exponent $n/2$ when $n$ is even, or with exponent $(n-1)/2$, when $n$ is odd. This gives us the recurrence relation</p>

\[T(n) = T(n/2) + O(1),\]

<p>where $O(1)$ represents the constant time operations (one or two multiplications per call). By the master method<sup><a href="#ref1">[1]</a></sup>, this yields a $O(\log_2 n)$ time complexity.</p>

<p>Below is an example of the algorithm implemented iteratively in C++:</p>

<div class="language-cpp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">int</span> <span class="nf">power</span><span class="p">(</span><span class="kt">int</span> <span class="n">base</span><span class="p">,</span> <span class="kt">int</span> <span class="n">exp</span><span class="p">)</span> <span class="p">{</span>
    <span class="kt">int</span> <span class="n">result</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span>
    <span class="k">while</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span>
        <span class="k">if</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&amp;</span> <span class="mi">1</span><span class="p">)</span> <span class="n">result</span> <span class="o">=</span> <span class="n">result</span> <span class="o">*</span> <span class="n">base</span><span class="p">;</span> <span class="c1">// If exp is odd, multiply by the base</span>
        <span class="n">base</span> <span class="o">=</span> <span class="n">base</span> <span class="o">*</span> <span class="n">base</span><span class="p">;</span>                  <span class="c1">// Square the base</span>
        <span class="n">exp</span> <span class="o">&gt;&gt;=</span> <span class="mi">1</span><span class="p">;</span>                           <span class="c1">// Halve the exponent</span>
    <span class="p">}</span>
    <span class="k">return</span> <span class="n">result</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<p>In effect, we’re processing the binary representation of $n$ bit by bit, from least significant (rightmost) to most significant (leftmost). We can write any non-negative integer $n$ in binary by expressing it as a sum of powers of $2$:</p>

\[n = b_0\cdot 2^0 + b_1\cdot 2^1 + b_2\cdot 2^2 + \dots + b_k\cdot 2^k,\]

<p>where each $b_i \in { 0, 1 }$ is the $i$th binary digit of $n$. For example,</p>

\[27 = 1\cdot 2^0+1\cdot 2^1+0\cdot 2^2+1\cdot 2^3+1\cdot 2^4 = 11011_2,\]

<p>where the subscript-$2$ notation denotes a binary representation. With this in mind, we can write</p>

\[\begin{align*}
x^n &amp;= x^{b_02^0 + b_12^1 + b_22^2 + \dots + b_k2^k} \\
&amp;= \prod_{i=0}^k (x^{2^i})^{b_i}.
\end{align*}\]

<p>This latter formula works as a neat summary of the fast exponentiation algorithm. At iteration $i$, the variable <code class="language-plaintext highlighter-rouge">base</code> holds $x^{2^i}$. If $b_i = 1$ (the exponent’s $i$th bit is 1), the algorithm multiplies this into <code class="language-plaintext highlighter-rouge">result</code>. If $b_i = 0$, the algorithm skips this multiplication. In both cases, it squares <code class="language-plaintext highlighter-rouge">base</code> to move from $x^{2^i}$ to $x^{2^{i+1}}$ for the next iteration.</p>

<p>To make this process more clear, consider the example when we want to compute $3^{13}$, so $x = 3$ and $n = 13$. When we write $n$ in binary, we are expressing it as a sum of powers of $2$, so $13$ is represented in binary as $1101_2$:</p>

\[13 = 8 + 4 + 1 = 2^3 + 2^2 + 2^0.\]

<p>The walkthrough of the algorithm’s execution for this example is as follows:</p>

<table>
  <thead>
    <tr>
      <th>Step</th>
      <th>Current exp (binary)</th>
      <th>Lowest bit</th>
      <th>Action on <code class="language-plaintext highlighter-rouge">result</code></th>
      <th>New result</th>
      <th>Next base (squared)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>$1101_2$ ($13$)</td>
      <td>1</td>
      <td>Multiply by $3$</td>
      <td>$1\cdot 3 = 3$</td>
      <td>$3^2 = 9$</td>
    </tr>
    <tr>
      <td>2</td>
      <td>$110_2$ ($6$)</td>
      <td>0</td>
      <td>Skip</td>
      <td>$3$</td>
      <td>$9^2 = 81$</td>
    </tr>
    <tr>
      <td>3</td>
      <td>$11_2$ ($3$)</td>
      <td>1</td>
      <td>Multiply by $81$</td>
      <td>$3\cdot 81=243$</td>
      <td>$81^2 = 6561$</td>
    </tr>
    <tr>
      <td>4</td>
      <td>$1_2$ ($1$)</td>
      <td>1</td>
      <td>Multiply by $6561$</td>
      <td>$243 \cdot 6561$</td>
      <td>done (exp is $0$)</td>
    </tr>
  </tbody>
</table>

<p>The final result we end up with is $243 \cdot 6561 = 1594323$.</p>

<h2 id="modular-exponentiation">Modular Exponentiation</h2>

<p>We can extend the above approach to instead raise one number to a power modulo another number, which is known as <strong>modular exponentiation</strong>. Formally, given a non-negative integer base $x$, a non-negative integer exponent $n$ and a positive integer modulus $m$, we want to efficiently compute the value $x^n \text{ mod } m$. Modular exponentation is crucial in many number-theoretic computations, including in primality-testing and in the RSA (Rivest–Shamir–Adleman) cryptosystem.</p>

<p>Practically, efficient modular exponentiation involves the same algorithm as fast exponentiation, but with modulo operations added at each step. Note that these modulo operations can safely be applied without threatening the correctness of the result because the modulo operation is distributive over multiplication, meaning that</p>

\[(a\cdot b) \text{ mod } m = (a \text{ mod } m) \cdot (b \text{ mod } m) \text{ mod } m,\]

<p>for non-negative integers $a, b$ and positive integer $m$.</p>

<p>Below is an example of modular exponentation implemented in C++:</p>
<div class="language-cpp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">int</span> <span class="nf">power</span><span class="p">(</span><span class="kt">int</span> <span class="n">base</span><span class="p">,</span> <span class="kt">int</span> <span class="n">exp</span><span class="p">,</span> <span class="kt">int</span> <span class="n">mod</span><span class="p">)</span> <span class="p">{</span>
    <span class="kt">int</span> <span class="n">result</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span>
    <span class="n">base</span> <span class="o">%=</span> <span class="n">mod</span><span class="p">;</span>                                           <span class="c1">// Initial modulo operation</span>
    <span class="k">while</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span>
        <span class="k">if</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&amp;</span> <span class="mi">1</span><span class="p">)</span> <span class="n">result</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">result</span> <span class="o">*</span> <span class="n">base</span><span class="p">)</span> <span class="o">%</span> <span class="n">mod</span><span class="p">;</span> <span class="c1">// Modulo after multiplying</span>
        <span class="n">base</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">base</span> <span class="o">*</span> <span class="n">base</span><span class="p">)</span> <span class="o">%</span> <span class="n">mod</span><span class="p">;</span>                  <span class="c1">// Modulo after squaring</span>
        <span class="n">exp</span> <span class="o">&gt;&gt;=</span> <span class="mi">1</span><span class="p">;</span>
    <span class="p">}</span>
    <span class="k">return</span> <span class="n">result</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<p>By performing modulo operations at each step, we keep intermediate values manageable, reducing the cost of calculation and preventing a potential overflow.</p>

<h2 id="leetcode-2438-range-product-queries-of-powers">LeetCode 2438. Range Product Queries of Powers</h2>

<p>Finally, we apply modular exponentiation to a the LeetCode problem <a href="https://leetcode.com/problems/range-product-queries-of-powers/description/">2438. Range Product Queries of Powers</a>. The problem statement is as follows:</p>

<blockquote>
  <p>Given a positive integer <code class="language-plaintext highlighter-rouge">n</code>, there exists a <code class="language-plaintext highlighter-rouge">0</code>-indexed array called <code class="language-plaintext highlighter-rouge">powers</code>, composed of the minimum number of powers of $2$ that sum to $n$. The array is sorted in non-decreasing order, and there is only one way to form the array.</p>

  <p>You are also given a <code class="language-plaintext highlighter-rouge">0</code>-indexed 2D integer array <code class="language-plaintext highlighter-rouge">queries</code>, where <code class="language-plaintext highlighter-rouge">queries[i] = [left_i, right_i]</code>. Each <code class="language-plaintext highlighter-rouge">queries[i]</code> represents a query where you have to find the product of all <code class="language-plaintext highlighter-rouge">powers[j]</code> with <code class="language-plaintext highlighter-rouge">left_i &lt;= j &lt;= right_i</code>.</p>

  <p>Return an array answers, equal in length to queries, where <code class="language-plaintext highlighter-rouge">answers[i]</code> is the answer to the <code class="language-plaintext highlighter-rouge">i</code>th query. Since the answer to the <code class="language-plaintext highlighter-rouge">i</code>th query may be too large, each <code class="language-plaintext highlighter-rouge">answers[i]</code> should be returned modulo $10^9 + 7$.</p>
</blockquote>

<p>The brute force solution would involve performing up to $32$ multiplications for each query, because the length of the <code class="language-plaintext highlighter-rouge">powers</code> array is bounded above by $32$, and then performing a modulo operation on the result we get at the end. Not only does this require a high constant factor to process each query, but it also requires multiplying very large numbers, which is costly and risks overflow.</p>

<p>We can use a prefix product array to achieve efficient processing of each query. However, the naive implementation of a prefix product array without performing intermediate modulo operations still requires multiplying large numbers and therefore risks overflow, and we can’t just perform intermediate modulo operations because the modulo operation is not distributive over division.</p>

<p>To solve this problem, we can apply Fermat’s Little Theorem. The statement is as follows:</p>

<blockquote>
  <p>Let $m$ be prime and $x$ be an integer such that $x$ and $m$ are coprime. Then
\(\begin{equation*}
x^{m-1} \text{ mod } m = 1.
\end{equation*}\)</p>
</blockquote>

<p>Readers well versed in number theory will recognize that this is a special case of Euler’s Theorem, because for any prime $m$, we have $\phi(m) = m - 1$. From Fermat’s Little Theorem, it immediately follows that</p>

\[\begin{equation*}
a \cdot a^{m-2} \text{ mod } m = 1.
\end{equation*}\]

<p>In other words, we know that modulo $m$, $a^{m-2}$ is the <em>multiplicative inverse</em> of $a$, so we can write that</p>

\[\begin{equation*}
a^{-1} \text{ mod } m = a^{m-2} \text{ mod } m.
\end{equation*}\]

<p>This means that, for any integer $b$ which is coprime to $m$, we have</p>

\[\begin{align*}
b / a \text{ mod } m &amp;= b \cdot a^{-1} \text{ mod } m \\
&amp;= b \cdot a^{m-2} \text{ mod } m.
\end{align*}\]

<p>Observe that $10^9 + 7$ is prime (this can be verified by the reader). Thus, we can apply the above result, efficiently precomputing the multiplicative inverse for each element in the prefix array using  modular exponentiation.</p>

<p>The solution in its entirety is below, implemented in C++:</p>

<div class="language-cpp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// OJ: leetcode.com/problems/range-product-queries-of-powers/description/</span>
<span class="c1">// Author: github.com/theoteske</span>
<span class="c1">// Time: O(Q)</span>
<span class="c1">// Space: O(1)</span>
<span class="k">class</span> <span class="nc">Solution</span> <span class="p">{</span>
<span class="nl">private:</span>
    <span class="k">const</span> <span class="kt">int</span> <span class="n">MOD</span> <span class="o">=</span> <span class="mi">1000000007</span><span class="p">;</span>
    <span class="kt">int</span> <span class="n">modPower</span><span class="p">(</span><span class="kt">long</span> <span class="kt">long</span> <span class="n">base</span><span class="p">,</span> <span class="kt">long</span> <span class="kt">long</span> <span class="n">exp</span><span class="p">)</span> <span class="p">{</span>
        <span class="kt">int</span> <span class="n">result</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span>
        <span class="n">base</span> <span class="o">%=</span> <span class="n">MOD</span><span class="p">;</span>
        <span class="k">while</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">if</span> <span class="p">(</span><span class="n">exp</span> <span class="o">&amp;</span> <span class="mi">1</span><span class="p">)</span> <span class="n">result</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">result</span> <span class="o">*</span> <span class="n">base</span><span class="p">)</span> <span class="o">%</span> <span class="n">MOD</span><span class="p">;</span>
            <span class="n">base</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">base</span> <span class="o">*</span> <span class="n">base</span><span class="p">)</span> <span class="o">%</span> <span class="n">MOD</span><span class="p">;</span>
            <span class="n">exp</span> <span class="o">&gt;&gt;=</span> <span class="mi">1</span><span class="p">;</span>
        <span class="p">}</span>
        <span class="k">return</span> <span class="n">result</span><span class="p">;</span>
    <span class="p">}</span>
<span class="nl">public:</span>
    <span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;</span> <span class="n">productQueries</span><span class="p">(</span><span class="kt">int</span> <span class="n">n</span><span class="p">,</span> <span class="n">vector</span><span class="o">&lt;</span><span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;&gt;&amp;</span> <span class="n">queries</span><span class="p">)</span> <span class="p">{</span>
        <span class="c1">// Construct powers array</span>
        <span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;</span> <span class="n">powers</span><span class="p">;</span>
        <span class="k">for</span> <span class="p">(</span><span class="kt">int</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span> <span class="n">i</span> <span class="o">&lt;=</span> <span class="mi">31</span><span class="p">;</span> <span class="o">++</span><span class="n">i</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">if</span> <span class="p">((</span><span class="mi">1</span> <span class="o">&lt;&lt;</span> <span class="n">i</span><span class="p">)</span> <span class="o">&amp;</span> <span class="n">n</span><span class="p">)</span> <span class="n">powers</span><span class="p">.</span><span class="n">push_back</span><span class="p">(</span><span class="mi">1</span> <span class="o">&lt;&lt;</span> <span class="n">i</span><span class="p">);</span>
        <span class="p">}</span>

        <span class="c1">// Construct prefix product array</span>
        <span class="k">const</span> <span class="kt">int</span> <span class="n">P</span> <span class="o">=</span> <span class="n">powers</span><span class="p">.</span><span class="n">size</span><span class="p">();</span>
        <span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;</span> <span class="n">prefix</span><span class="p">(</span><span class="n">P</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="mi">1</span><span class="p">);</span>
        <span class="k">for</span> <span class="p">(</span><span class="kt">int</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span> <span class="n">i</span> <span class="o">&lt;=</span> <span class="n">P</span><span class="p">;</span> <span class="o">++</span><span class="n">i</span><span class="p">)</span> <span class="p">{</span>
            <span class="n">prefix</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">prefix</span><span class="p">[</span><span class="n">i</span> <span class="o">-</span> <span class="mi">1</span><span class="p">]</span> <span class="o">*</span> <span class="n">powers</span><span class="p">[</span><span class="n">i</span> <span class="o">-</span> <span class="mi">1</span><span class="p">])</span> <span class="o">%</span> <span class="n">MOD</span><span class="p">;</span>
        <span class="p">}</span>

        <span class="c1">// Precompute multiplicative inverses under mod for each value in prefix</span>
        <span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;</span> <span class="n">inverse</span><span class="p">;</span>
        <span class="n">inverse</span><span class="p">.</span><span class="n">reserve</span><span class="p">(</span><span class="n">P</span> <span class="o">+</span> <span class="mi">1</span><span class="p">);</span>
        <span class="k">for</span> <span class="p">(</span><span class="kt">int</span> <span class="n">num</span> <span class="o">:</span> <span class="n">prefix</span><span class="p">)</span> <span class="p">{</span>
            <span class="n">inverse</span><span class="p">.</span><span class="n">push_back</span><span class="p">(</span><span class="n">modPower</span><span class="p">(</span><span class="n">num</span><span class="p">,</span> <span class="n">MOD</span> <span class="o">-</span> <span class="mi">2</span><span class="p">));</span>
        <span class="p">}</span>

        <span class="c1">// Process queries</span>
        <span class="k">const</span> <span class="kt">int</span> <span class="n">Q</span> <span class="o">=</span> <span class="n">queries</span><span class="p">.</span><span class="n">size</span><span class="p">();</span>
        <span class="n">vector</span><span class="o">&lt;</span><span class="kt">int</span><span class="o">&gt;</span> <span class="n">ans</span><span class="p">(</span><span class="n">Q</span><span class="p">);</span>
        <span class="k">for</span> <span class="p">(</span><span class="kt">int</span> <span class="n">i</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span> <span class="n">i</span> <span class="o">&lt;</span> <span class="n">queries</span><span class="p">.</span><span class="n">size</span><span class="p">();</span> <span class="o">++</span><span class="n">i</span><span class="p">)</span> <span class="p">{</span>
            <span class="n">ans</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1LL</span> <span class="o">*</span> <span class="n">prefix</span><span class="p">[</span><span class="n">queries</span><span class="p">[</span><span class="n">i</span><span class="p">][</span><span class="mi">1</span><span class="p">]</span><span class="o">+</span><span class="mi">1</span><span class="p">]</span> <span class="o">*</span> <span class="n">inverse</span><span class="p">[</span><span class="n">queries</span><span class="p">[</span><span class="n">i</span><span class="p">][</span><span class="mi">0</span><span class="p">]])</span> <span class="o">%</span> <span class="n">MOD</span><span class="p">;</span>
        <span class="p">}</span>

        <span class="k">return</span> <span class="n">ans</span><span class="p">;</span>
    <span class="p">}</span>
<span class="p">};</span>
</code></pre></div></div>

<hr />

<h2 id="references">References</h2>

<ol>
  <li><a id="ref1"></a>Cormen, T. H., Leiserson, C. E., Rivest, R. L., &amp; Stein, C. (2022). <em>Introduction to Algorithms</em> (4th ed.). MIT Press.</li>
</ol>]]></content><author><name>Theo Teske</name></author><category term="Modular Exponentiation" /><category term="LeetCode" /><category term="Number Theory" /><category term="C++" /><category term="LaTeX" /><summary type="html"><![CDATA[I give an exposition of both the fast exponentiation and modular exponentiation algorithms, then we apply the latter to the LeetCode problem 2438. Range Product Queries of Powers. The solution to this problem presented here differs substantially from the solution provided in the LeetCode editorial while still achieving optimal runtime and memory efficiency.]]></summary></entry><entry><title type="html">Sample Technical Post Demonstrating Math and Code</title><link href="https://theoteske.github.io/blog/2025/08/sample-technical-post/" rel="alternate" type="text/html" title="Sample Technical Post Demonstrating Math and Code" /><published>2025-08-22T00:00:00-05:00</published><updated>2025-08-22T00:00:00-05:00</updated><id>https://theoteske.github.io/blog/2025/08/sample-technical-post</id><content type="html" xml:base="https://theoteske.github.io/blog/2025/08/sample-technical-post/"><![CDATA[<p>This is a sample post demonstrating the technical capabilities of my Jekyll blog, including LaTeX math rendering and syntax-highlighted code blocks.</p>

<h2 id="math-with-latex">Math with LaTeX</h2>

<h3 id="inline-math">Inline Math</h3>

<p>We can write inline math like $E = mc^2$ or $\sum_{i=1}^{n} x_i$ directly in our text.</p>

<h3 id="display-math">Display Math</h3>

<p>For larger equations, we use display math:</p>

\[\frac{\partial L}{\partial \theta} = \frac{1}{m} \sum_{i=1}^{m} (h_\theta(x^{(i)}) - y^{(i)}) \cdot x^{(i)}.\]

<h3 id="complex-equations">Complex Equations</h3>

<p>Here’s the quadratic formula:</p>

\[x = \frac{-b \pm \sqrt{b^2 - 4ac}}{2a}.\]

<p>Here is an aligned set of equations:</p>

\[\begin{align*}
(x+2)^2 &amp;= (x+2)(x+2) \\
&amp;= x^2 + 4x + 4.
\end{align*}\]

<p>And here is a matrix example:</p>

\[\begin{bmatrix}
a_{11} &amp; a_{12} &amp; \cdots &amp; a_{1n} \\
a_{21} &amp; a_{22} &amp; \cdots &amp; a_{2n} \\
\vdots &amp; \vdots &amp; \ddots &amp; \vdots \\
a_{m1} &amp; a_{m2} &amp; \cdots &amp; a_{mn}
\end{bmatrix}\]

<h2 id="code-examples">Code Examples</h2>

<h3 id="python-code">Python Code</h3>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">fibonacci</span><span class="p">(</span><span class="n">n</span><span class="p">):</span>
    <span class="s">"""Generate Fibonacci sequence up to n terms."""</span>
    <span class="k">if</span> <span class="n">n</span> <span class="o">&lt;=</span> <span class="mi">0</span><span class="p">:</span>
        <span class="k">return</span> <span class="p">[]</span>
    <span class="k">elif</span> <span class="n">n</span> <span class="o">==</span> <span class="mi">1</span><span class="p">:</span>
        <span class="k">return</span> <span class="p">[</span><span class="mi">0</span><span class="p">]</span>
    <span class="k">elif</span> <span class="n">n</span> <span class="o">==</span> <span class="mi">2</span><span class="p">:</span>
        <span class="k">return</span> <span class="p">[</span><span class="mi">0</span><span class="p">,</span> <span class="mi">1</span><span class="p">]</span>
    
    <span class="n">fib_sequence</span> <span class="o">=</span> <span class="p">[</span><span class="mi">0</span><span class="p">,</span> <span class="mi">1</span><span class="p">]</span>
    <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">2</span><span class="p">,</span> <span class="n">n</span><span class="p">):</span>
        <span class="n">next_num</span> <span class="o">=</span> <span class="n">fib_sequence</span><span class="p">[</span><span class="n">i</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span> <span class="o">+</span> <span class="n">fib_sequence</span><span class="p">[</span><span class="n">i</span><span class="o">-</span><span class="mi">2</span><span class="p">]</span>
        <span class="n">fib_sequence</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">next_num</span><span class="p">)</span>
    
    <span class="k">return</span> <span class="n">fib_sequence</span>
</code></pre></div></div>

<h3 id="javascript-code">JavaScript Code</h3>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// Implementing a binary search tree</span>
<span class="kd">class</span> <span class="nx">Node</span> <span class="p">{</span>
    <span class="kd">constructor</span><span class="p">(</span><span class="nx">value</span><span class="p">)</span> <span class="p">{</span>
        <span class="k">this</span><span class="p">.</span><span class="nx">value</span> <span class="o">=</span> <span class="nx">value</span><span class="p">;</span>
        <span class="k">this</span><span class="p">.</span><span class="nx">left</span> <span class="o">=</span> <span class="kc">null</span><span class="p">;</span>
        <span class="k">this</span><span class="p">.</span><span class="nx">right</span> <span class="o">=</span> <span class="kc">null</span><span class="p">;</span>
    <span class="p">}</span>
<span class="p">}</span>

<span class="kd">class</span> <span class="nx">BinarySearchTree</span> <span class="p">{</span>
    <span class="kd">constructor</span><span class="p">()</span> <span class="p">{</span>
        <span class="k">this</span><span class="p">.</span><span class="nx">root</span> <span class="o">=</span> <span class="kc">null</span><span class="p">;</span>
    <span class="p">}</span>
    
    <span class="nx">insert</span><span class="p">(</span><span class="nx">value</span><span class="p">)</span> <span class="p">{</span>
        <span class="kd">const</span> <span class="nx">newNode</span> <span class="o">=</span> <span class="k">new</span> <span class="nx">Node</span><span class="p">(</span><span class="nx">value</span><span class="p">);</span>
        
        <span class="k">if</span> <span class="p">(</span><span class="k">this</span><span class="p">.</span><span class="nx">root</span> <span class="o">===</span> <span class="kc">null</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">this</span><span class="p">.</span><span class="nx">root</span> <span class="o">=</span> <span class="nx">newNode</span><span class="p">;</span>
            <span class="k">return</span> <span class="k">this</span><span class="p">;</span>
        <span class="p">}</span>
        
        <span class="kd">let</span> <span class="nx">current</span> <span class="o">=</span> <span class="k">this</span><span class="p">.</span><span class="nx">root</span><span class="p">;</span>
        <span class="k">while</span> <span class="p">(</span><span class="kc">true</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">if</span> <span class="p">(</span><span class="nx">value</span> <span class="o">&lt;</span> <span class="nx">current</span><span class="p">.</span><span class="nx">value</span><span class="p">)</span> <span class="p">{</span>
                <span class="k">if</span> <span class="p">(</span><span class="nx">current</span><span class="p">.</span><span class="nx">left</span> <span class="o">===</span> <span class="kc">null</span><span class="p">)</span> <span class="p">{</span>
                    <span class="nx">current</span><span class="p">.</span><span class="nx">left</span> <span class="o">=</span> <span class="nx">newNode</span><span class="p">;</span>
                    <span class="k">return</span> <span class="k">this</span><span class="p">;</span>
                <span class="p">}</span>
                <span class="nx">current</span> <span class="o">=</span> <span class="nx">current</span><span class="p">.</span><span class="nx">left</span><span class="p">;</span>
            <span class="p">}</span> <span class="k">else</span> <span class="p">{</span>
                <span class="k">if</span> <span class="p">(</span><span class="nx">current</span><span class="p">.</span><span class="nx">right</span> <span class="o">===</span> <span class="kc">null</span><span class="p">)</span> <span class="p">{</span>
                    <span class="nx">current</span><span class="p">.</span><span class="nx">right</span> <span class="o">=</span> <span class="nx">newNode</span><span class="p">;</span>
                    <span class="k">return</span> <span class="k">this</span><span class="p">;</span>
                <span class="p">}</span>
                <span class="nx">current</span> <span class="o">=</span> <span class="nx">current</span><span class="p">.</span><span class="nx">right</span><span class="p">;</span>
            <span class="p">}</span>
        <span class="p">}</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<h3 id="bashshell-script">Bash/Shell Script</h3>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">#!/bin/bash</span>
<span class="c"># Script to backup important files</span>

<span class="nv">SOURCE_DIR</span><span class="o">=</span><span class="s2">"/home/user/documents"</span>
<span class="nv">BACKUP_DIR</span><span class="o">=</span><span class="s2">"/backup/documents"</span>
<span class="nv">DATE</span><span class="o">=</span><span class="si">$(</span><span class="nb">date</span> +%Y%m%d_%H%M%S<span class="si">)</span>

<span class="c"># Create backup directory if it doesn't exist</span>
<span class="nb">mkdir</span> <span class="nt">-p</span> <span class="s2">"</span><span class="nv">$BACKUP_DIR</span><span class="s2">"</span>

<span class="c"># Perform backup</span>
<span class="nb">tar</span> <span class="nt">-czf</span> <span class="s2">"</span><span class="nv">$BACKUP_DIR</span><span class="s2">/backup_</span><span class="nv">$DATE</span><span class="s2">.tar.gz"</span> <span class="s2">"</span><span class="nv">$SOURCE_DIR</span><span class="s2">"</span>

<span class="c"># Keep only last 7 backups</span>
<span class="nb">ls</span> <span class="nt">-t</span> <span class="s2">"</span><span class="nv">$BACKUP_DIR</span><span class="s2">"</span>/backup_<span class="k">*</span>.tar.gz | <span class="nb">tail</span> <span class="nt">-n</span> +8 | xargs <span class="nb">rm</span> <span class="nt">-f</span>

<span class="nb">echo</span> <span class="s2">"Backup completed: backup_</span><span class="nv">$DATE</span><span class="s2">.tar.gz"</span>
</code></pre></div></div>

<h2 id="algorithm-analysis">Algorithm Analysis</h2>

<p>Let’s analyze the time complexity of the Fibonacci function above. The recursive implementation has a time complexity of $O(2^n)$, while our iterative approach has:</p>

<ul>
  <li><strong>Time Complexity</strong>: $O(n)$</li>
  <li><strong>Space Complexity</strong>: $O(n)$</li>
</ul>

<p>We can improve the space complexity to $O(1)$ by only keeping track of the last two numbers:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">fibonacci_optimized</span><span class="p">(</span><span class="n">n</span><span class="p">):</span>
    <span class="k">if</span> <span class="n">n</span> <span class="o">&lt;=</span> <span class="mi">0</span><span class="p">:</span>
        <span class="k">return</span> <span class="mi">0</span>
    <span class="k">elif</span> <span class="n">n</span> <span class="o">==</span> <span class="mi">1</span><span class="p">:</span>
        <span class="k">return</span> <span class="mi">1</span>
    
    <span class="n">prev</span><span class="p">,</span> <span class="n">curr</span> <span class="o">=</span> <span class="mi">0</span><span class="p">,</span> <span class="mi">1</span>
    <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">2</span><span class="p">,</span> <span class="n">n</span> <span class="o">+</span> <span class="mi">1</span><span class="p">):</span>
        <span class="n">prev</span><span class="p">,</span> <span class="n">curr</span> <span class="o">=</span> <span class="n">curr</span><span class="p">,</span> <span class="n">prev</span> <span class="o">+</span> <span class="n">curr</span>
    
    <span class="k">return</span> <span class="n">curr</span>
</code></pre></div></div>

<h2 id="combining-math-and-code">Combining Math and Code</h2>

<p>Consider the following implementation of gradient descent:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">numpy</span> <span class="k">as</span> <span class="n">np</span>

<span class="k">def</span> <span class="nf">gradient_descent</span><span class="p">(</span><span class="n">X</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">theta</span><span class="p">,</span> <span class="n">alpha</span><span class="p">,</span> <span class="n">iterations</span><span class="p">):</span>
    <span class="s">"""
    Performs gradient descent to learn theta.
    
    Args:
        X: input features (m x n matrix)
        y: target values (m x 1 vector)
        theta: parameters (n x 1 vector)
        alpha: learning rate
        iterations: number of iterations
    """</span>
    <span class="n">m</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">y</span><span class="p">)</span>
    
    <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">iterations</span><span class="p">):</span>
        <span class="c1"># Hypothesis: h = X * theta
</span>        <span class="n">h</span> <span class="o">=</span> <span class="n">X</span><span class="p">.</span><span class="n">dot</span><span class="p">(</span><span class="n">theta</span><span class="p">)</span>
        
        <span class="c1"># Calculate the cost J(theta)
</span>        <span class="n">cost</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1</span><span class="o">/</span><span class="p">(</span><span class="mi">2</span><span class="o">*</span><span class="n">m</span><span class="p">))</span> <span class="o">*</span> <span class="n">np</span><span class="p">.</span><span class="nb">sum</span><span class="p">((</span><span class="n">h</span> <span class="o">-</span> <span class="n">y</span><span class="p">)</span><span class="o">**</span><span class="mi">2</span><span class="p">)</span>
        
        <span class="c1"># Calculate gradient
</span>        <span class="n">gradient</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1</span><span class="o">/</span><span class="n">m</span><span class="p">)</span> <span class="o">*</span> <span class="n">X</span><span class="p">.</span><span class="n">T</span><span class="p">.</span><span class="n">dot</span><span class="p">(</span><span class="n">h</span> <span class="o">-</span> <span class="n">y</span><span class="p">)</span>
        
        <span class="c1"># Update parameters
</span>        <span class="n">theta</span> <span class="o">=</span> <span class="n">theta</span> <span class="o">-</span> <span class="n">alpha</span> <span class="o">*</span> <span class="n">gradient</span>
        
        <span class="k">if</span> <span class="n">i</span> <span class="o">%</span> <span class="mi">100</span> <span class="o">==</span> <span class="mi">0</span><span class="p">:</span>
            <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Iteration </span><span class="si">{</span><span class="n">i</span><span class="si">}</span><span class="s">: Cost = </span><span class="si">{</span><span class="n">cost</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
    
    <span class="k">return</span> <span class="n">theta</span>
</code></pre></div></div>

<p>The cost function being minimized is:</p>

\[J(\theta) = \frac{1}{2m} \sum_{i=1}^{m} (h_\theta(x^{(i)}) - y^{(i)})^2\]

<p>Where $h_\theta(x) = \theta^T x$ is our hypothesis function.</p>]]></content><author><name>Theo Teske</name></author><category term="Tutorial" /><category term="LaTeX" /><category term="Python" /><category term="JavaScript" /><category term="Markdown" /><summary type="html"><![CDATA[This is a sample post demonstrating the technical capabilities of my Jekyll blog, including LaTeX math rendering and syntax-highlighted code blocks.]]></summary></entry></feed>